|
Hello! I am a second-year CS PhD student at Stanford University, fortunate to be advised by Prof. Jiajun Wu in the Stanford Vision and Learning Lab. I am also a student researcher at Google in San Francisco. Previously, I completed my MS in Robotics and undergrad in CS at Carnegie Mellon University, advised by Prof. Deva Ramanan. My research is supported by the NSF Graduate Research Fellowship (2023-). I am interested in computer vision and its intersection with robotics, generative modeling, and representation learning. CV / Google Scholar / Github / Email / Twitter |
|
|
|
|
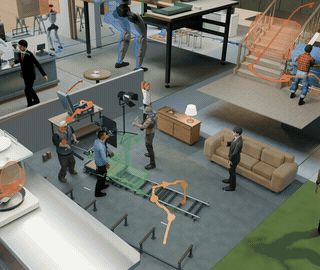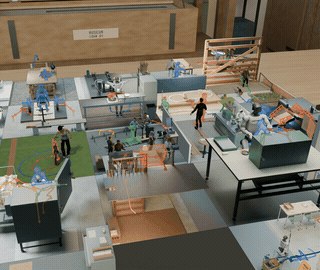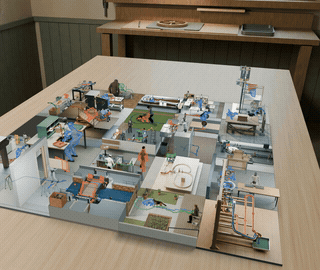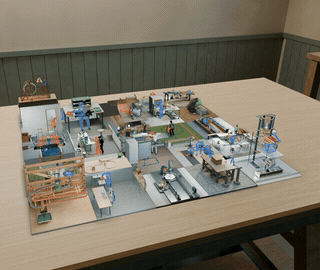
Jeff Tan*, Hang Dai*, Zeqian Long*, Yanzhe Lyu, R. Kenny Jones, Shangzhe Wu, Chen Geng†, Jiajun Wu† arXiv 2026 Website | arXiv | Github We generate minutes-long physically-plausible 3D animations from text, depicting humanoid robots, people, and mechanisms, with better quality than bare GPT-6 agents. |

|
Zihan Wang*, Jiashun Wang*, Jeff Tan, Yiwen Zhao, Jessica Hodgins, Shubham Tulsiani, Deva Ramanan ICLR 2026 Website | arXiv | Github We recover high-quality and simulation-ready scene geometry from Internet videos, for humanoid real-to-sim within complex terrains. |

|
Zihan Wang, Jeff Tan, Tarasha Khurana, Neehar Peri, Deva Ramanan ICCV 2025 Website | arXiv | Github We reconstruct dynamic 4D human-centric scenes (e.g. playing the piano and bicycle repair) from sparse-view video. |
|
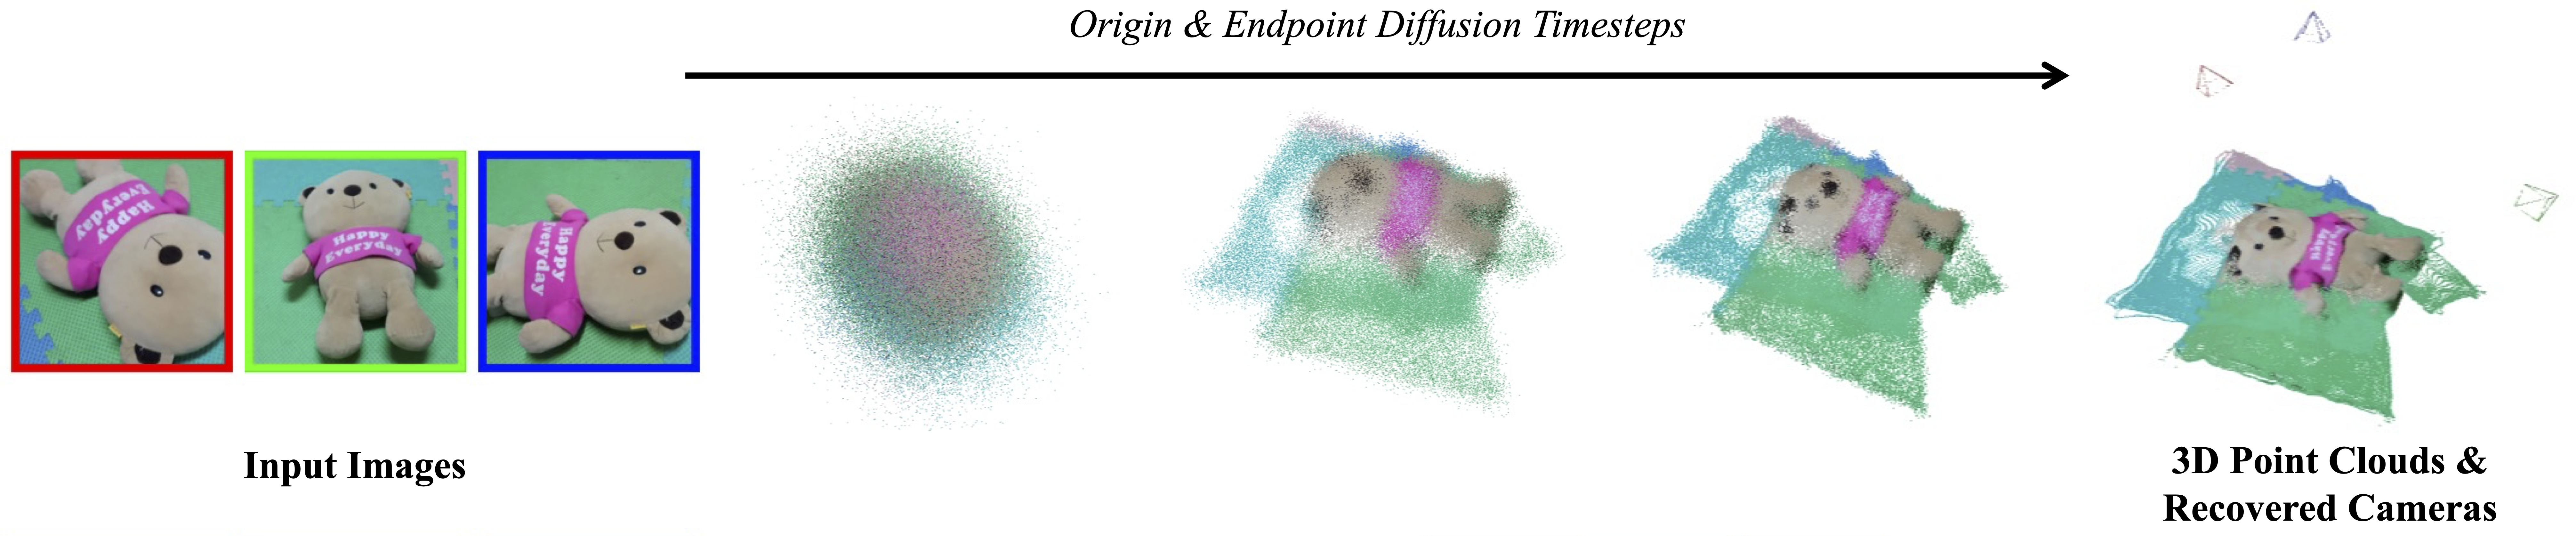
Qitao Zhao, Amy Lin, Jeff Tan, Jason Y. Zhang, Deva Ramanan, Shubham Tulsiani CVPR 2025 Website | arXiv | Github From a set of multi-view images, we learn a denoising diffusion model that outputs scene geometry and cameras in global frame. |

|
Jeff Tan, Donglai Xiang, Shubham Tulsiani, Deva Ramanan, Gengshan Yang 3DV 2025 (Oral) Website | arXiv | Github From a single monocular video, we reconstruct humans in loose clothing and interacting with objects, using a hierarchical deformation field and image-based priors. |
 
|
Jeff Tan, Gengshan Yang, Deva Ramanan CVPR 2023 Website | Paper | Github We learn real-time feed-forward pose and shape predictors, by distilling knowledge from offline differentiable rendering optimizers. |
|
|
|
Gengshan Yang, Jeff Tan, Alex Lyons, Neehar Peri, Deva Ramanan 2023 Website | Github A Python library for 4D reconstruction of humans, animals, and scenes from monocular videos. |
|
|
|
Teaching Assistant, Physics-Based Rendering (15-468): S23, S24
Teaching Assistant, Parallel Computation (15-418): F21, S22, S23 Teaching Assistant, Introduction to Computer Systems (15-213): F21 |
|
Credits to Jon Barron for this website's template. |